Text, image, video, audio, sensorHuman-labeled training data
99%+annotation accuracy
28languages
17.5K+agents worldwide
40+locations
13countries
What is data annotation
Models are only as smart as the data they learn from.
Great AI starts with great data. Fusion CX turns raw text, images, video, audio and sensor data into clean, human-labeled training data, from RLHF to physical AI training data for robots, in 28 languages with 99%+ accuracy.
Data annotation labels and tags raw data so machines can understand it, from drawing boxes around objects to tagging sentiment or transcribing speech. Outsourcing it lets your engineers focus on building models instead of labeling by hand.
Every project runs on Omind AI’s platforms: Annotera.AI for multimodal data labeling and RLHF, and Roborax.AI for physical AI and robotics training data, with human-in-the-loop quality control in one connected pipeline.
Text
Image
Video
Audio
Sensor
From solo builders to enterprise MLResearchers, enterprise ML teams and robotics companies
Why Fusion CX for data annotation
More than labeling: we train AI and deploy it.
We run live customer experience operations for global brands, and we put that understanding of real human interactions to work in our labeling.
01
Dedicated teams, not crowdsourcing
The same trained annotators work on your project, so quality and context stay consistent.
02
A closed-loop AI advantage
With 17.5K+ agents across global operations, Fusion CX both trains AI and deploys it.
03
Global scale and 28 languages
A multi-country delivery network handles high-volume, multilingual projects without sacrificing accuracy.
04
99%+ accuracy through layered QA
Annotator review, team-lead spot checks and independent QA catch errors before delivery.
Our data annotation services
Every major data type, labeled by trained annotators.
Each project runs through a layered quality process, so what you get back is ready to train on.
Text annotation
Named entity recognition, sentiment tagging, intent classification and semantic labeling for search, chatbots and LLMs.
Image annotation
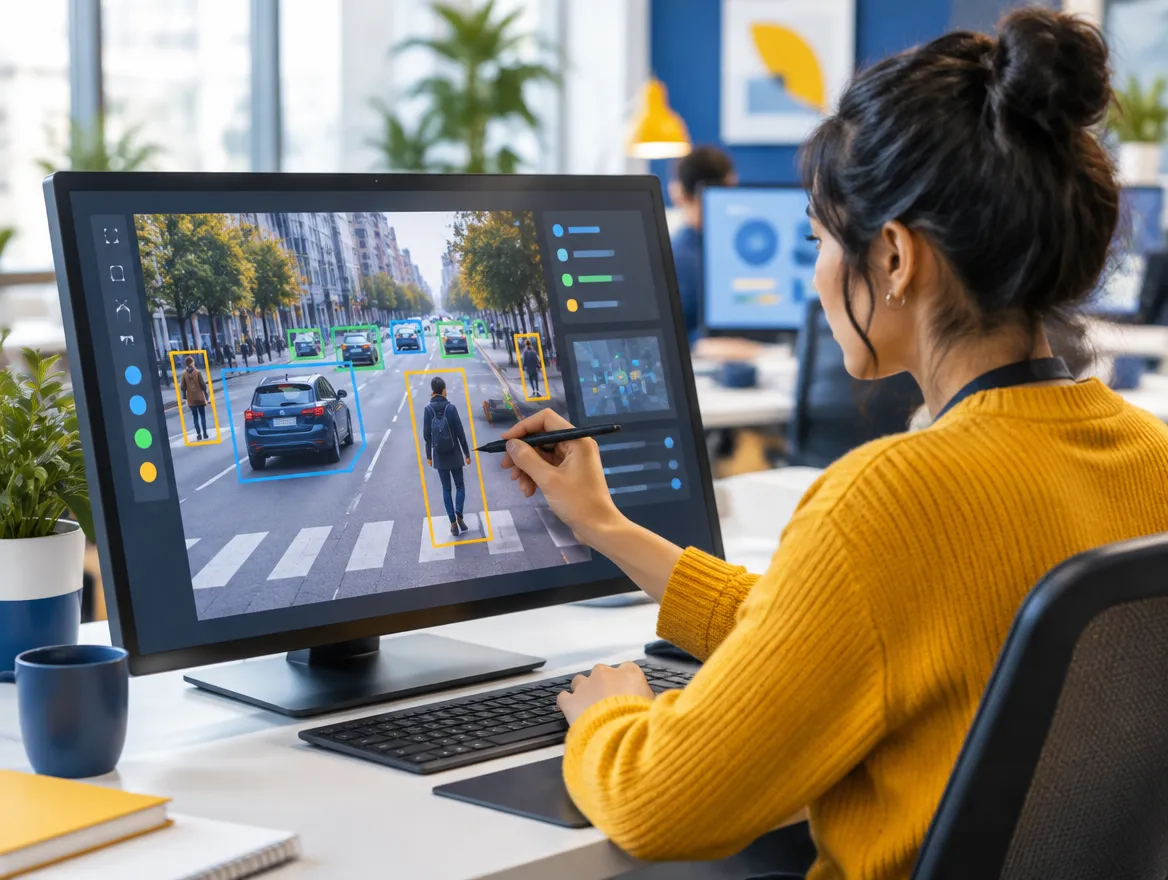
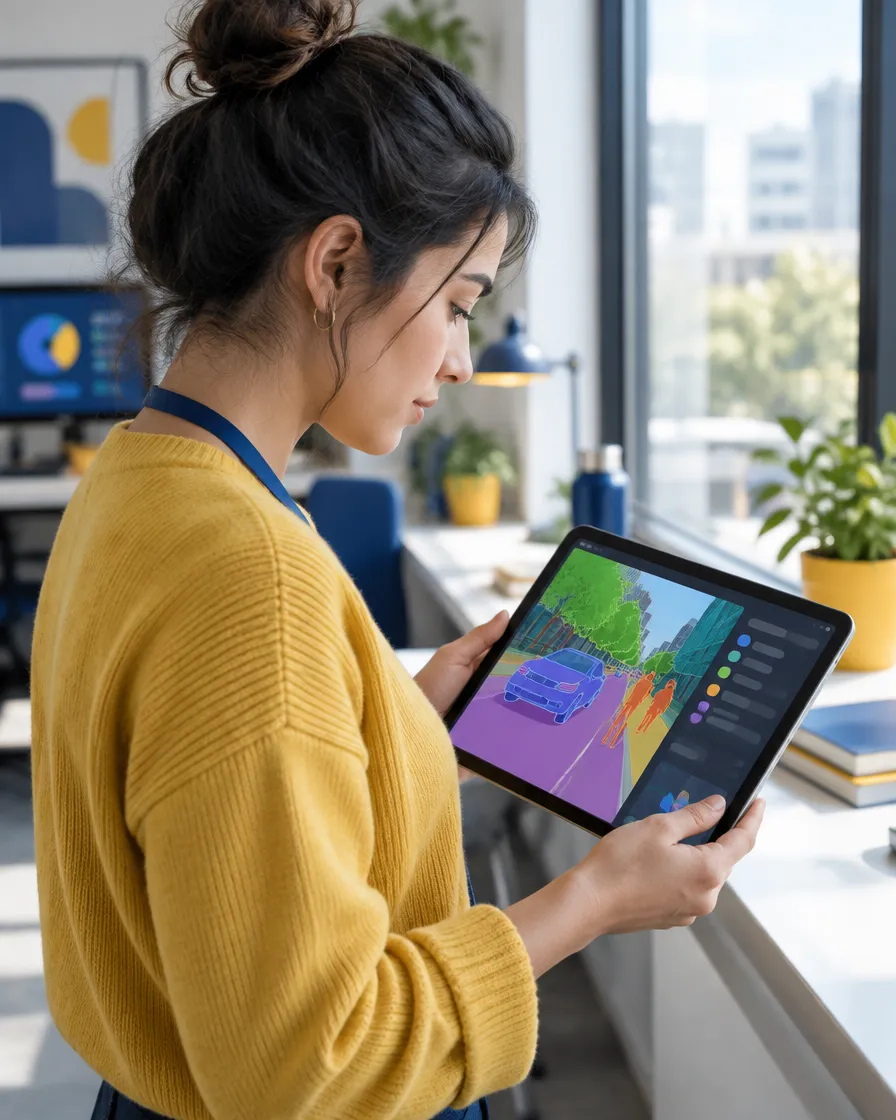
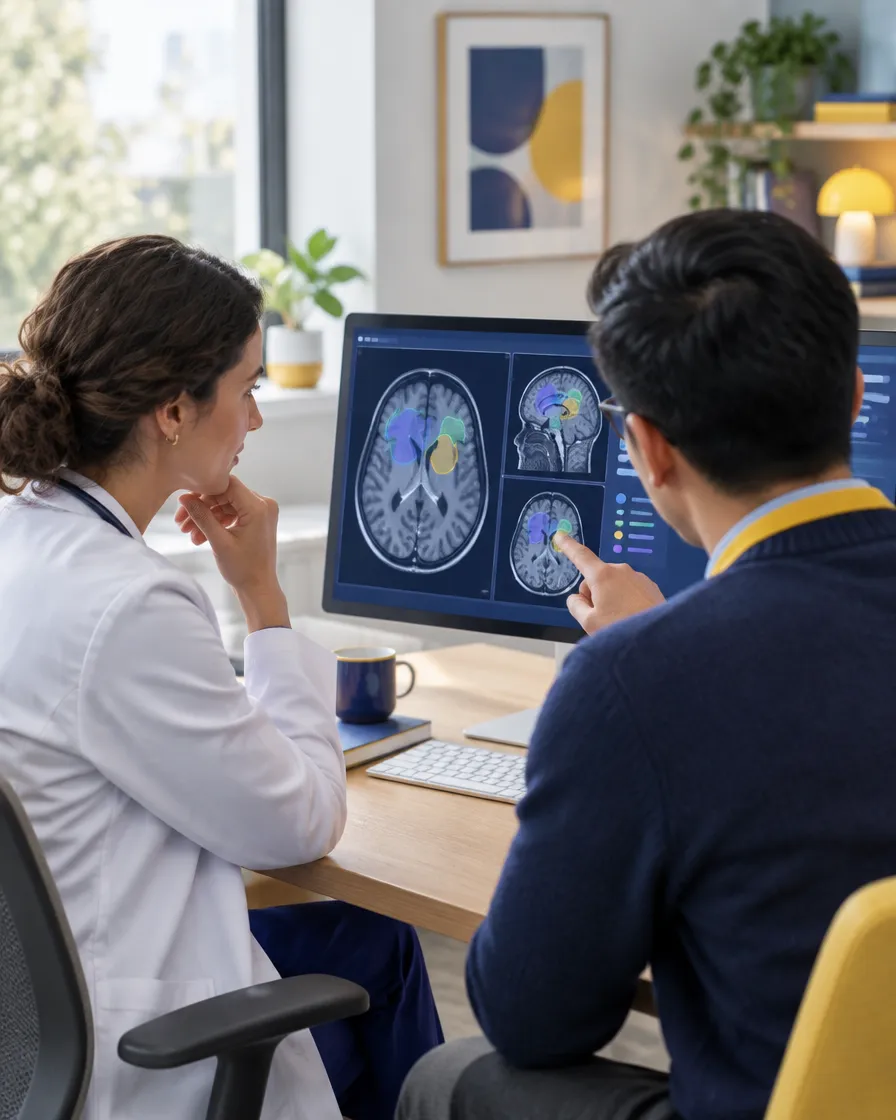
Bounding boxes, polygons, semantic segmentation and keypoint labeling for computer vision, from catalogs to medical imaging.
Video annotation
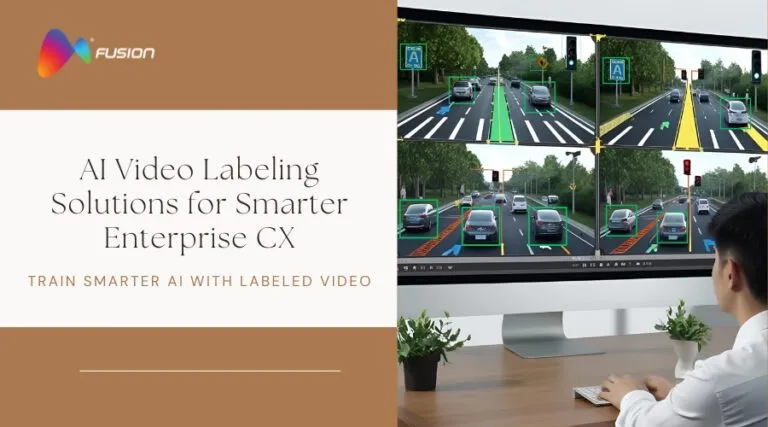
Frame-by-frame object tracking, event tagging and multi-object labeling for autonomous systems and behavior analysis.
Audio and speech annotation
Transcription, speaker identification, sentiment and intent labeling across accents and languages for voice AI.
RLHF and generative AI
Human feedback, prompt and response ranking, red-teaming and content moderation to align LLMs with human judgment.
Our annotation and AI training data services power models where accuracy and privacy matter most.
01
Autonomous vehicles and robotics
Perception, navigation and safety data for machines operating in the real world.
02
Healthcare and life sciences
Medical imaging and clinical text annotation, with privacy-first workflows.
03
Retail and ecommerce
Product catalogs, visual search and review sentiment labeling.
04
Banking and financial services
Training data for fraud detection, document processing and risk models.
05
Security and surveillance
Object and event detection in video.
Get in touch
Talk to our data annotation team.
Tell us about your data types, volumes and accuracy targets. We’ll scope a pilot or an enterprise pipeline for your models and respond within one business day.
What industries do you cater to with your data annotation services?
We offer data annotation customized for industries including autonomous vehicles and robotics, healthcare and life sciences, retail and ecommerce, banking and financial services, and security and surveillance.
What types of data can Fusion CX annotate?
We annotate text, images, video, audio and sensor data, including named entity recognition, bounding boxes, semantic segmentation, transcription, RLHF and physical AI training data for robotics.
What is RLHF and do you provide it?
RLHF (Reinforcement Learning from Human Feedback) is a training method where humans rank and rate model outputs to align AI behavior with human judgment. Yes, we provide RLHF, prompt and response ranking, and red-teaming for large language models.
How does Fusion CX ensure annotation quality?
Every project runs through a layered quality process: annotator self-review, team-lead spot checks and independent QA. This is how we reach 99%+ accuracy across large, multilingual projects.
Can you support robotics and physical AI projects?
Yes. We offer watchers, resolvers and teleoperation services to capture, guide and correct real-world robot behavior, feeding corrected data straight back into model training.
Who can use your services?
Both individual contributors training their own AI models and B2B or enterprise teams building production ML systems. We scale from small pilot projects to high-volume enterprise pipelines.